
-
v30001-THE 88% - Finding the Race Within the Race (Video)Dave, in the session you described that there were only 4 races out of 16 where you used the 88. So if the 88 is so important, I'm not clear as to what you are doing in the other 12 races. It seems that in those cases you are using the 88 to determine that we should not be using the 88 due to that particular race structure. Is that correct? I think I need a better understanding of "race structure". — Jeff Capper
Really excellent question.
Think about the ways that were introduced last night to ELIM one or more of the bottom horses...
@ponyplayer called it. "The race within the race... within the race..."
Think of it like breaking the log jam at the BOTTOM to create a new race.
Or... consider @Jim Pommier and how he has (historically) used his PSR objects.
Not saying you must use PSR.
Consider that WHALE-friendly objects push winners to the top... and losers to the bottom.
So, imagine somewhat top-driven objects that will do the opposite... push LOSERS to the BOTTOM... which allows you to pick a horse or two who are already NEAR the bottom... and eliminate them with reasonable confidence.
Then you apply Brian's idea... Race within a race... within a race... within a race. -
Horizontal WageringThis is why I look for a single to wager - it keeps costs down and I can still make a little bit of money if all D horses come in. — Bill Rudnicki
I don't see how that strategy can possibly produce long-term profit. -
Horizontal Wagering
This is a great topic - and one I won't be much help with.
Not being a Horiz player, my best guess is that you must do some studying to figure out an optimum ticket structure for your particular style
For example... using 4 dL-horses would probably be a waste of money. -
discussion re: THE 88% - Finding the Race Within the RaceYou will have the remaining horses recalculated
as-if the d and L were never in the race. Unmarking
and recalculating does not remove them. Their numbers
are still lurking. — ponyplayer
I believe is correct.
They just never load if you uncheck the d and the L. -
discussion re: THE 88% - Finding the Race Within the RaceQuestion:
We can unclick the d and L before we Fire Core AI. Does that produce the same result as marking and removing them? Or are they lurking in the background and therefore messing up the "new race"? — Dale Oldham
In theory that should work.
Give it a try.
The only thing you don't get is the Hedge Threshold of the original field. -
Need some help with narrowing down contenders
Also, @Tony Kofalt gave you his answer.
Notice how his answer included a STRATEGY for addressing the problem.
That is probably what you're looking for...
What strategy are you currently using to get the odds ranges you're looking for? -
Need some help with narrowing down contendersWhat I am certain of is that my of top 4 contenders 1 is winning 78% of the time . What I think is going wrong is that I am unable to narrow them to one or two contenders some are won by class or early pace combining low and high neal so I need some help narrowing down the contenders to the winners — Ira Yorn
Examine the two questions again.
Being certain of an END RESULT is a good start. But the answer must be framed in the manner of "I am certain that doing THIS, AND THIS will get me 78% winners WITHIN MY TARGET RANGE OF HORSES."
I'll explain why...
Let's say that you are using the AI Line's top 88% to pick contenders.
(That will likely score you about 91% wins.)
However, it logically will often include 6 or 7 horses. So, in those cases it tells you nothing.
78% is a very good number... if it is usually no more than 3/4 horses. Beyond that, it isn't doing anything for you. That is, if it isn't scoring you the horses you are searching for.
______________________
I would think that the problem needs to be BETTER DEFINED.
Think of it like going through a grocery store. Imagine there are aisles containing handicapping approaches.
**High Hit Rate
They usually don't label "but Low Prices" because the high hit rate/low prices are dating on a regular basis.
**High Prices
"Low Hit Rate" can be assumed, right?
__________________
Reconsider the question "What I think is going wrong is..."
What do you think the CAUSE of this is? -
Need some help with narrowing down contenders
Maybe start by describing what you're currently doing.
Start with this question:
"What am I certain of right now?
Then this question:
"What I think is going wrong is..." -
Post Key Data error
Yes, bad downloads do happen.
When you get that error, just notice which file it choked on.
1. You don't have to abort. Just let it run.
Just take a screenshot of the file with the problem so you know what needs fixing.
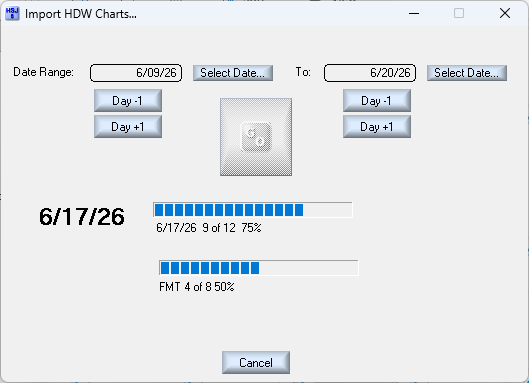
Like this one that I had on June 17. See where it stopped?
2. When the entire process completes...
A. Download the bad file.
B. Run HSD
C. Import Charts for just that single day.
The PPs are already imported and they're fine, so you can jump straight to charts.
D. Post KEY DATA for that same day.
Maybe 2 or 3 times per year the problem will be a bad file as opposed to a bad downloaded.
If you get the same error again, escalate it to me and I'll get the file recreated from HDW. -
Post Key Data error
Wait... depends on when it was.
If it was during the import, it can be a PP file.
If it was in opening the day then the entire day file is lost.
Best to download all the files for that day and process them all again. -
Post Key Data errorSee how it says that the zip file does not exist?
Well, it doesn't exist because it was never imported.
I know... Everyone says, "I know I did."
100% of the time when I meet, the file simply does not exist. -
Saratoga around the cornerAnybody who wishes to join the panel should send me a private message for the zoom link.
-
Saratoga around the cornerI'd love to play live with you guys but just don't play enough races at one track.
Would you guys have any interest in an open mic panel? -
deTERMINATOR: Confidence Level vs. Score Problem
Beth leaves next Sunday for a trip to grandkids-land for a week.
Give me a call on my cell and we'll make a plan. -
deTERMINATOR: Confidence Level vs. Score ProblemAlso, and this is kind of a strange idea...
Do you know the paper, Attention is all you need? Well the way they keep words from inflating themselves to the detriment of the whole, is they require each matrix row to sum to 1. Words are still typically more attuned to themselves than the rest of the words in the array/sentence, but they are attentive enough to the words around them that there is meaning. Have you tried a mathematical approach in that manner with your genetic style algorithms that are limiting their guesses to "game" the rules? I wonder if there is a linear algebraic solution to your issue. — Daniel Boals
I'm sorry, but I do not understand what you mean.
Perhaps we should put one of those lunches at the Atlantis real soon.
BTW, we ate at the Chinese restaurant next to the buffet on Friday night. While the menu is very limited, the food was phenomenal. -
deTERMINATOR: Confidence Level vs. Score ProblemI take it you are using your own neural network in DET? I know you have experience with neural networks going back years, and when you started this project, there really weren't any open LLMs like we have today. I am no expert, but it seems like the neural nets in DeepSeek and Alibaba's Qwen are both pretty good and they have resources to train that you probably can't get without a billion dollar investment. Have you thought about using one of their models to check your DET? The new Qwen 3.6 29b is supposed to be really good. It is a dense model and it seems like what your are doing is more of a MoE, but then they do have Qwen 3.6 35b which is a MoE style logic under the hood. — Daniel Boals
First, I stopped using Neural Nets about 1994. They're not very good at "predictive AI." That is, they're not very good at accepting they can't get everything right.
(I write extremely advanced Genetic Algorithms.)
Second, when you upload racing data to an LLM, it absolutely DOES NOT use a Neural Network on it. Instead, it uses statistical methods.
Think of an LLM as a TRAINED tool. The LLM itself is not a NN. It is the OUTPUT of a NN.
Have you thought about using one of their models to check your DET?
Not for a second. LOL
...but it seems like the neural nets in DeepSeek and Alibaba's Qwen are both pretty good and they have resources to train that you probably can't get without a billion dollar investment.
The billion dollar investment could certainly have been used in other directions - but the goal was LANGUAGE, which is far different than making any kind of "investment prediction." -
Thistledown todayYes, races #10 and #11 from last year. GPX only had 9 races today. They usually then card a few races from I believe Argentina. Looks like maybe they thought there were 11 races today, but the last two (2) were from Argentina, not GPX. — Jim Pommier
Just heard from Ryan at HDW.
He says that they repaired today's GP file to remove the wrong races.
Dave Schwartz
Start FollowingSend a Message